How to develop safer, more transparent and responsible algorithms
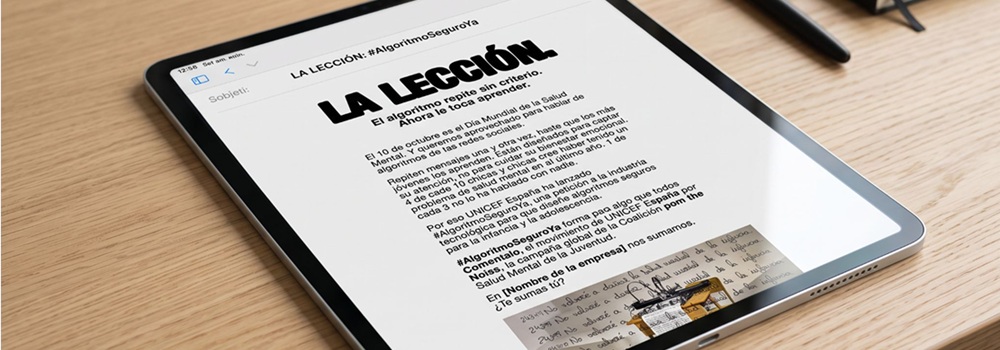
UNICEF Spain’s recent awareness campaign ‘Algoritmo Seguro Ya’, launched alongside the ‘La Lección’ initiative, has once again drawn attention to an issue that goes far beyond the everyday use of social media: the content children and adolescents receive is not presented at random, but is shaped by algorithmic systems designed to select, rank and recommend information.
Data from the Infancia, adolescencia y bienestar digital report underline the importance of this debate: 92.5% of adolescents in Spain use social media, almost 60% say they do not want an algorithm making decisions for them, and a significant proportion spend several hours a day in front of screens. This comes alongside growing concerns about the emotional wellbeing and mental health of younger users.
Behind these figures lies a fundamental technological question: recommendation algorithms are not neutral systems. Their behaviour depends on the data they use, the criteria established during their design and, above all, the objectives they have been optimised to achieve.
What happens behind a recommendation algorithm?
From a software engineering and data science perspective, recommendation engines are analytical systems designed to identify behavioural patterns and anticipate which content may be most relevant to each user.
To do this, they can analyse signals such as videos watched, searches performed, interactions, time spent viewing content or even pauses while browsing. Based on these data, models learn from previous interactions and progressively adjust the content they display, creating an increasingly personalised experience.
This recommendation logic is based on a continuous learning process. A particular interaction generates a signal; the system interprets that signal as a potential preference and modifies subsequent recommendations. If the user continues to interact with similar content, the model receives further evidence that reinforces that association.
This can lead to repetition-based feedback loops: recommendations influence what users consume and, in turn, that consumption feeds into subsequent recommendations. As a result, an initial preference can progressively gain greater weight within the profile the system builds for each individual.
This mechanism is not necessarily negative. Personalisation can reduce the amount of irrelevant information users receive and adapt services to their interests. The risk emerges when certain types of content become disproportionately prominent and the diversity of information received gradually decreases.
Understanding how this works is particularly important for vulnerable users such as children and adolescents, as repeated exposure to certain messages may have a greater impact on their perceptions, interests or behaviour.
Bias, amplification and the risks of design focused exclusively on attention
Once we understand how a recommendation algorithm learns and personalises content, the next question is what objective it is being asked to optimise. This is a key distinction: not all risks arise from the model’s learning process or from the data themselves. They can also result from decisions made during system design.
One example is attention maximisation bias, or engagement bias. This occurs when metrics such as time spent on the platform, number of clicks, interactions or frequency of use become the main indicators of success. Under these conditions, a system may end up favouring content that generates intense emotional responses or keeps users engaged for longer.
A second phenomenon is the emergence of information bubbles. Unlike the feedback loop described above, which explains how the system learns, this refers to a possible consequence of that dynamic: users may become exposed to an increasingly narrow range of topics, messages or perspectives. Personalisation can then move beyond simply improving relevance and become a mechanism for amplification.
This can be reinforced by design patterns intended to prolong use, which do not depend directly on the recommendation algorithm itself. Interface features such as infinite scrolling or autoplay reduce natural breaks in browsing and facilitate continuous content consumption. These are product design decisions that can amplify the effects of the recommendation system, even though they belong to a different layer of the platform.
It is therefore useful to distinguish between three levels: how the algorithm learns, what objectives it is asked to optimise, and how the surrounding user experience is designed. Feedback loops are part of the way the recommendation system operates; attention bias and information bubbles can emerge as possible effects of its optimisation objectives; and mechanisms such as infinite scrolling or autoplay belong to the platform’s design.
Analysing these layers separately makes it easier to understand where different risks originate and avoids attributing exclusively to the algorithm effects that may also depend on design choices, business metrics and interaction patterns.
From regulation to responsible AI system design
Building safer digital environments requires a combination of regulation, technological design and oversight mechanisms. From a technical perspective, models can be developed so that their performance is not measured solely in terms of engagement. Optimisation functions can incorporate variables related to content diversity, privacy, security or specific protection criteria, so that system success does not depend exclusively on time spent, frequency of use or number of clicks.
The incorporation of appropriate age-verification systems, tools to limit continuous exposure to certain types of content, or safeguards against potentially harmful patterns of use can introduce safety criteria directly into the architecture of the service.
Explainable Artificial Intelligence (XAI) techniques make it possible to better understand which factors influence a system’s results and facilitate its evaluation, auditing and oversight. When AI systems are involved in processes with significant consequences, maintaining human control mechanisms makes it possible to review results, identify unwanted behaviour and prevent sensitive decisions from depending exclusively on automated processes.
Moving towards more responsible AI ultimately means incorporating these principles from the design stage rather than adding them later as corrective measures. Regulation, optimisation criteria, technical safeguards, explainability and human oversight should all form part of the same architecture, designed to reduce risks and strengthen trust in digital systems..
Technologies for safer, more transparent and responsible AI
At Gradiant, we research and develop technologies that make it possible to apply artificial intelligence and analyse large volumes of data while incorporating privacy, security, transparency and human-control requirements from the design stage. These capabilities are particularly relevant in scenarios involving sensitive information or where AI-supported decisions may have consequences for individuals.
One of our areas of work focuses on developing models and architectures that incorporate principles of ethical and transparent AI, Explainable Artificial Intelligence techniques and mechanisms designed to prevent sensitive decisions from relying exclusively on automated processes. In these systems, AI can provide information, analysis and decision support, while final decisions remain under human supervision.
This approach is complemented by our capabilities in User and Entity Behaviour Analytics (UEBA) and Natural Language Processing (NLP), which we use to develop algorithms capable of analysing large volumes of information, detecting anomalies and identifying relevant patterns. These technologies make it possible to address complex phenomena in digital environments and extract useful information from heterogeneous sources, supported by architectures designed for large-scale data processing.
Privacy is also embedded in the technological architecture itself. At Gradiant, we work with decentralised analysis techniques and Federated Learning, enabling shared intelligence to be developed without having to centralise or directly expose private data sources. This makes it possible to combine the value of information with privacy requirements, regulatory compliance and responsible use of AI.
Another of our areas of work focuses on the secure exchange and analysis of information. Technologies such as AnonymiX enable personal data to be anonymised, while our capabilities in data spaces support interoperable environments in which information can be shared and used in a controlled manner. These are complemented by data-quality assurance techniques and architectures capable of processing large volumes of heterogeneous information.
These capabilities are being applied, among other areas, in PRESERVE, a European initiative led by Gradiant that focuses on developing decision-support tools for law enforcement authorities. The work combines privacy, ethical AI, decentralised analysis and advanced data processing to address scenarios such as the prevention and investigation of child sexual abuse, the identification of hate speech, the analysis of radicalisation processes and the early detection of activities linked to drug trafficking.
In the area of child protection, for example, analysis and visualisation tools are being developed to help understand relationships between potential perpetrators, victims and associated networks, always within a decision-support model rather than an automated decision-making system.
This European initiative, funded by Horizon Europe, provides an opportunity to bring these technologies into real-world scenarios and validate them alongside law enforcement authorities from different European countries.
Towards safer algorithms by design
UNICEF’s #AlgoritmoSeguroYa initiative highlights the fact that protecting children and adolescents in digital environments cannot depend solely on how they use online platforms. We must also ask how the systems that select, prioritise and amplify the information they receive are designed.
Technology makes it possible to move towards different models: more transparent systems, privacy-preserving analysis mechanisms, decentralised architectures, explainable AI and processes in which people retain control over decisions. At Gradiant, these are precisely the capabilities we are working on to demonstrate that advanced artificial intelligence can be developed without compromising privacy, security or the responsible use of data.
Building safer digital environments requires these principles to be incorporated from the very moment an algorithm is designed.
The project has received funding from the European Union’s Horizon Europe research and innovation programme under grant agreement No 101168309.